Repo: the document store
Repo is ProtoMolt's claim-check document store. The bulky bytes of a document live in S3-compatible object storage; a Postgres catalog records every revision of every document and the stored objects each revision points at. Documents are split into independently addressable parts, so a reader can fetch a few kilobytes of metadata without dragging the multi-megabyte payload along.
Boot a demo repository locally (gRPC on 9090, HTTP upload on 8080)
docker run --rm -p 9090:9090 -p 8080:8080 \
  pipestreamai/protomolt-serve --demo
The Docker image and the Mac DMG (protomolt-serve.app, Apple silicon, with its
own bundled Java runtime) run the same one-process server, and both serve the
DocumentService described on this page.
flowchart LR
        step["A pipeline step"] -->|"node id + requested parts"| repo["repo-service"]
        repo --> pg["Postgres catalog: revisions, part references, outcomes"]
        repo --> obj["S3-compatible storage: write-once part and blob objects"]
        obj -->|"only the parts asked for"| repo
        repo -->|"assembled document"| step
The DocumentService contract
Callers reach the store through one gRPC service,
ai.protomolt.proto.repo.v2.DocumentService. It is
parts-based: a save names the parts it changes, a read names the parts it
wants, and every committed save becomes a numbered revision. The contract
borrows a library word for one committed revision, an accession: an item
formally entered into the collection, never edited afterward. Seventeen RPCs cover the whole
lifecycle:
| Job | RPCs |
|---|---|
| Write | SaveDocument; SaveDocuments (bulk stream, one response per request, correlated by request id); UploadDocument (raw file or encoded part, admitted from its header before any byte is staged) |
| Read | GetDocument (unary); ReadDocument (streamed, verified parts); ReadDocuments (bulk stream); ReadBlob (one raw file, optional byte range) |
| Inspect | GetManifest; GetSchemaDescriptor (a retained descriptor set, by digest); ListRevisions; ListDocuments (lookup fields, typed filters, sort); GetOperationOutcome |
| Follow links | ListLinks (a revision's links, with each static target's state for this reader); ResolveLink (one page of a dynamic link's targets); ListBacklinks (static links into a document) |
| Remove | DeleteDocument (a tombstone revision); PurgeDocument (administrative byte removal) |
In the bulk streams one document's failure never fails the stream: each item ends in its own result or its own error. The HTTP upload route on port 8080 is another surface onto the same upload operation, and the same port serves the repository's browser console.
One document, five parts
A stored Document is not one blob. The codec splits it on clean protobuf
field boundaries into five kinds of parts: CORE, BLOBS, PARSED, one CHUNKS
object per segmentation, and one EMBEDDINGS object per embedding set. Each part is its own
stored object, and every part gets a SHA-256 entry in the revision's manifest. A reader
names the parts it wants, and the full document reassembles byte-for-byte from the
fragments, merged in manifest order. The round-trip tests compare bytes to prove it.
The split is descriptor-driven, not hardcoded to
Document: the codec reads a PartLayout that says which field is
the identity, which fields form which part, and which part is chunked and sub-keyed. Any
protobuf message type can be decomposed the same way. Click through the parts below
to see what each one holds and when it is fetched.
Document message, split on field boundaries. Click a part (or a field)
to see what it holds, who reads it, and when its bytes are fetched.
The document's fields
doc_ididentity, derived deterministicallyownershipaccount and security contextsearch_metadataminus its semantic_resultsstructured_datatyped extracted fieldssemantic_resultsolder chunk list, refused on savesegmentationsone object per segmentationembedding_setsone object per embedding setblob_bagreferences to the raw bytesparser_resultseverything parsers emitted
Parts on the drive
CORE selected by part
Holds: the doc_id and how it is derived, ownership,
structured_data, and search_metadata except
semantic_results.
Read by: nearly every step. This part and the catalog row are the two things most calls touch.
Fetched when: almost any read. A search hit needs CORE alone and never touches the megabytes in BLOBS.
BLOBS selected by part; raw files by blob id
Holds: blob_bag, the claim checks for the raw files.
Each raw file is its own stored object, bound by the server to the blob's id. On read
the server fills the blob's storage_ref (the claim check),
size_bytes, SHA-256 checksum and checksum_type
from that binding, plus written: the revision, commit time and producing
step of the write that bound it. A client never supplies storage_ref or
written.
Read by: parsers, and anyone who needs the original file back.
ReadBlob streams one raw file, optionally a byte range of it.
Fetched when: only when a caller asks for raw bytes. A metadata lookup never fetches this part.
CHUNKS selected by segmentation_id
Holds: one object per entry of
search_metadata.segmentations, keyed by its
segmentation_id. The codec still knows the older
semantic_results chunk list, but a save that carries it is refused with a
message to write segmentations and embedding sets instead.
Read by: retrieval steps that need the text or embedding chunks.
Fetched when: a read names that segmentation. Other sets stay on the drive untouched.
PARSED selected by part
Holds: parser_results, the append-only exhaust of
everything the parsers produced.
Read by: downstream steps that want parsed structure without re-running a parser.
Fetched when: a read requests PARSED explicitly.
EMBEDDINGS selected by embedding set key
Holds: one object per search_metadata.embedding_sets
entry, keyed by its segmentation and embedding set id. The manifest records the
segmentation digest each set is bound to.
Read by: indexing and retrieval steps that need the vectors.
Fetched when: a read names that embedding set.
A revision's manifest lists every part it has in codec order, requested or not, with each part's state: present, intentionally empty, or deleted.
repo/codec PartLayouts.java, the default layout for Document (CORE is everything unmapped)
PartLayout.builder(documentType)
        .identityField("doc_id")
        .partField(DocumentPart.DOCUMENT_PART_BLOBS, "blob_bag")
        .partField(DocumentPart.DOCUMENT_PART_PARSED, "parser_results")
        .chunkedPart(DocumentPart.DOCUMENT_PART_CHUNKS,
                "search_metadata.semantic_results", "result_id")
        .keyedPart(DocumentPart.DOCUMENT_PART_CHUNKS,
                "search_metadata.segmentations", "segmentation_id")
        .keyedPart(DocumentPart.DOCUMENT_PART_EMBEDDINGS,
                "search_metadata.embedding_sets", "segmentation_id", "embedding_set_id")
        .build();
Saves and reads both work in parts. A save lists its writes: each named
part is either PUT with new content, marked EMPTY (present and intentionally empty), or
marked DELETED with a reason. A save can also take a part from an exact revision of
another address holding the same doc_id; the new revision references the
same stored object, so nothing is copied. Every part neither written nor sourced carries
forward from the revision the caller expected to replace, and content sent for a part
that is not listed as a PUT is rejected, never silently dropped.
A partial read assembles only the requested parts, chunk sets, and
embedding sets. GetManifest fetches no payloads at all: it reports the
revision's committed_at and, for each part, its state, size, SHA-256, the
revision that wrote it with that revision's commit time (written_at), and
who wrote it. Carried parts keep their original writer and time, so the manifest always
names the step or intake datasource that actually produced the bytes. A part written
before commit times were recorded has no written_at.
Raw files can be carried individually too. In a BLOBS PUT, a blob with no
data that is not the streamed upload names a blob of the expected revision
by its blob_id: the save keeps that blob's binding and its
written stamp without resending or copying the bytes, and the commit fails
as SOURCE_PURGED if the object was purged in the meantime. A
blob_id the expected revision does not have, or such a blob on a create, is
a malformed request. A save that sets written, a
checksum_type other than SHA-256, or a size_bytes or
checksum that disagrees with the bytes is refused: as a malformed request for
inline and carried blobs, and as a recorded UPLOAD_MISMATCH for a streamed
one. A blob's schema_subject (up to 300 characters) names which protobuf
message its bytes decode as; the repository records it as sent and does not enforce it,
leaving registry enforcement to a gate in front of the repository.
Identity: a four-part call number with a history
A document's identity is not a random id and not the raw doc_id string. The
contract calls it the call number, another library term: a
NodeAddress made of four logical segments, the document id, the graph
address id, the owning account id, and the graph id. The graph segment matters because
two independent pipelines can give different nodes the same name; including the graph id
keeps their stored documents distinct, so one pipeline finishing its own work can never
disturb another's in-flight copy. An intake save can name only its datasource, and the
service fills in the rest from the document's own id and ownership.
Each call number has one current-revision pointer, and history lives under it. Revisions
count up from 1, each records the revision it replaced, and none is edited after it is
written. ListRevisions pages through that history newest first, and any read
can pin an exact revision; asking for a revision that does not exist is
NOT_FOUND, never a quiet fallback to the current one.
repo/proto address.proto: the four segments of the call number
Show the actual definition
// The storage identity of one stored document state: the four logical
// segments the deterministic node id (UUIDv5) is derived from. This is THE
// way to address a row; node_id strings are derived echoes, never truth.
message NodeAddress {
  string doc_id = 1;
  string graph_address_id = 2;  // datasource id at intake, graph node id in a pipeline
  string account_id = 3;        // owning account (tenant root)
  string graph_id = 4;          // "intake:<accountId>" at intake, owning graph id in a pipeline
}
The catalog enforces the model in SQL. The four segments form a unique identity, blank segments are unrepresentable, and a revision can only point backward:
repo/catalog, the catalog schema (abridged)
-- The call number and its current-revision pointer: the compare-and-set row.
UNIQUE (account_id, graph_id, graph_address_id, doc_id)
-- One accession. Revisions, part references and outcomes are immutable once written.
CHECK (previous_revision >= 0 AND previous_revision < revision)
Retries and racing writers cannot double-write
Every save carries a client-chosen operation_id, unique per account, and the
outcome is recorded under it. A retry with the same id and the same request gets the
recorded outcome back with replayed=true instead of writing a second
revision; the same id with a different request is a conflict. A caller that lost its
connection and cannot tell whether a save landed asks GetOperationOutcome,
which has exactly three answers: committed (the accession, or the recorded rejection),
nothing recorded yet (which is not a failure, since an outstanding request may still
commit), or lookup unavailable.
Every save also states the revision it expects to replace, and there is no unconditional option. A create expects none; an update pins the exact revision it read. Two writers racing on one document cannot silently overwrite each other: the second one conflicts and has to reread.
repo/proto v2 manifest.proto: the expected revision every save carries
Show the actual definition
// The caller's view of the document's current revision. There is
// no unconditional option.
message ExpectedRevision {
  oneof expected {
    // The document must not exist yet.
    bool none = 1;
    // The current revision must equal this.
    int64 revision = 2;
  }
}
Bytes are checked on the way in and on the way out. The storage layer computes each
object's SHA-256 and length itself while writing, never trusting a digest the caller
supplied, and every write lands on a new key, so nothing stored is ever overwritten.
Reads re-verify retained bytes against the manifest before answering. A streamed
ReadDocument ends with a completion frame, and a prefix without it does not
count as success; a full ReadBlob ends with a SHA-256 check and fails with
DATA_LOSS on a mismatch.
repo/stack Stack.java, the storage contract
// One configured storage namespace, written once per key.
// Every put creates a new key and never overwrites; the stack computes the
// SHA-256 and length itself, so a reference never trusts a caller's digest.
StackRef put(InputStream body, long expectedLength) throws IOException;
Reads that buffer bytes draw on a fixed per-host budget,
DOCUMENT_PLATFORM_READ_BUDGET_BYTES (256 MiB by default). A read that does
not fit the remaining budget is refused at once with RESOURCE_EXHAUSTED
instead of being queued, so concurrent verified reads stay under one byte ceiling.
Saves draw on a second pool of the same size. Once a save has been split into its
fragments and its inline blobs extracted, the bytes it holds for the write are reserved
against the save budget, and a save that does not fit is refused with
RESOURCE_EXHAUSTED ("Save buffer budget exhausted") rather than queued.
Reads and saves do not compete for one pool, so the worst case a host reserves for both
together is twice DOCUMENT_PLATFORM_READ_BUDGET_BYTES.
UploadDocument is a bidirectional stream that answers before any payload
byte is staged. Its first frame is a header carrying the save, and the server validates
it and runs ownership, owner match, writer authority and the revision checks on it; a
refusal ends the call before any data is sent. A body small enough to ride in the header
frame (inline_data) commits in that same round trip and is answered
saved. A streamed body is answered replayed, with
the recorded outcome and no data sent, when its operation id has already committed the
same intent. Otherwise it is answered accepted, the data frames follow under
gRPC flow control, and the client's half-close is answered saved. A streamed
upload can carry its finished CORE in an UploadTrailer after the last data
frame. The trailer may change CORE content only, and ownership derivation, owner match
and writer authority run again on it before the one commit. Each call commits or is
withdrawn exactly once: the commit and any refusal or cancellation settle through one
compare-and-set, so a call answered with an error never commits and a committing call is
never answered with a refusal.
repo/proto v2 document_service.proto: the upload handshake
// One answer of an upload: accepted, then saved; or replayed; or saved alone
// for an inline body.
message UploadDocumentResponse {
  oneof answer {
    SaveDocumentResponse saved = 1;
    UploadAccepted accepted = 2;
    SaveDocumentResponse replayed = 3;
  }
}
Large source files take the HTTP upload route, POST /v1/documents:upload.
The request body streams into the drive's storage with no in-memory buffering and lands
as the raw file of a new revision, saved through the same pipeline as
UploadDocument. Every request carries a caller: the operator API token, or a
scoped credential or console session resolved the same way as on the gRPC listener; a
request with neither answers 401 and an account the caller is not bound to answers 403.
The upload header is checked before the server reads the body, so a refused request is
answered without its bytes being staged. Content-Length is required (the route answers 411 without it). An optional
X-Content-Sha256 is verified while the bytes stream, a stable
operation_id makes a retry replay instead of duplicate, and
expected_revision pins the revision an update means to advance. A client
that sends Accept: application/proto gets the binary
UploadDocumentResponse back, and an error keeps its HTTP status with the
gRPC status in grpc-status and a binary ItemError body; any
other client gets a small JSON receipt:
repo README: the upload receipt
{
  "operation_id": "…",
  "doc_id": "…",
  "revision": 1,
  "replayed": false,
  "size_bytes": 8388608,
  "sha256": "…"
}
Admission: what a save must prove before it lands
Nothing is written until a save is admitted. Admission covers three checks, and each failure has a fixed status and a fixed answer to the question "was this recorded?"
- Structure. Proto validation (required fields, CEL message rules)
plus the service's own checks: no selector named twice, content only for parts listed
as PUT, no part both written and sourced. A failure is
INVALID_ARGUMENTand records nothing. - Schema. The service assembles the whole candidate revision (written,
sourced, and carried parts together, so rules that span parts see the whole document),
decodes it fragment by fragment under retained schemas, resolves every
google.protobuf.Anyit finds, and evaluates the document's CEL rules. Semantic parts get their own checks: a segmentation's segments must match the text they span, and an embedding set must bind to the segmentation digest and segment ids it claims. - Authorization. The caller's account, the document's access rules, and, for a pipeline step's save, its writer grant, checked live at commit and kept on the revision as evidence.
Every admitted revision carries a recorded verdict. TYPED_VALID means every
Any resolved, decoded, and validated. OPAQUE_ACCEPTED is the
only other content verdict, and it takes two keys: the save asks for
VALIDATION_MODE_OPAQUE_ALLOWED and the host's policy permits it. Even then
each value the service cannot decode must be accounted for: named by an attestation
(a typed path to the occurrence plus its exact type URL), attributed to a producing step
under an active writer grant, or carried forward byte for byte from an earlier
committed occurrence. Those bytes are stored undecoded and are never reported as
typed-valid, and a typed read of a part that holds them fails unless the reader sets
allow_opaque.
repo/proto v2 manifest.proto: the verdict every revision records
Show the actual definition
enum ValidationStatus {
  // Never recorded.
  VALIDATION_STATUS_UNSPECIFIED = 0;
  // Every rule evaluated and passed; no opaque content.
  VALIDATION_STATUS_TYPED_VALID = 1;
  // Accepted with opaque occurrences; never reported as typed-valid.
  VALIDATION_STATUS_OPAQUE_ACCEPTED = 2;
  // Tombstones authorize a delete and make no content-validation claim.
  VALIDATION_STATUS_NOT_APPLICABLE = 3;
}
Rejections split cleanly. A schema, semantic, or payload-rule failure is a
recorded outcome: the rejection commits under the operation id and the
call answers FAILED_PRECONDITION, so a retry with the same id replays the
rejection instead of running admission again. Malformed requests, permission failures,
and revision conflicts record nothing, with one deliberate exception: a refused opaque
save (OPAQUE_NOT_ALLOWED, a PERMISSION_DENIED) is recorded,
while a refused write grant is not. On the bulk streams the same refusal arrives as one
item's error, never as a failed stream.
The schemas a revision was admitted under stay with it. The validation record names each
one by the SHA-256 of its retained descriptor bytes, and
GetSchemaDescriptor returns that exact FileDescriptorSet, with
its complete import closure, so a reader years later can decode a part with the schema
it was written under rather than whatever the registry says today. The digest grants
nothing by itself: it must be referenced by the named revision's validation record, and
the caller must be able to read that document. A digest the caller cannot reach answers
NOT_FOUND with the same code and message as one that does not exist, and
the bytes are hashed again before they are sent. Sets can reach the 16 MiB retained
ceiling, above the 4 MiB inbound default of stock gRPC clients, so a client that reads
large sets raises its limit.
repo/proto v2 document_service.proto: a retained schema read
rpc GetSchemaDescriptor(GetSchemaDescriptorRequest)
    returns (GetSchemaDescriptorResponse);
// request:  address (the call number), revision (unset = current),
//           descriptor_sha256 (as recorded on the revision)
// response: revision, descriptor_sha256, descriptor_set (verified bytes)
Finding documents: lookup fields, typed filters, sort
ListDocuments pages through the current documents of one account,
optionally scoped to a datasource or graph. Each row carries the document's
lookup fields: a small projection of its current CORE part that the
catalog keeps beside the revision (title, document type, source URI and MIME type,
language, author, category, creation and modification dates, the metadata map, and the
owning datasource and connector), plus the save owner of the current revision. When a
save leaves CORE unchanged, the catalog carries the lookup forward; a tombstone or purge
drops it. The projection is rebuildable from the stored parts and is never the source of
truth.
Filters are typed protobuf fields, never a query language. Every field set must hold, and each is an exact match on the current revision: document id, title, type, source URI, MIME type, language, author, category, datasource, connector, up to 50 metadata key/value pairs, a commit-time window (inclusive after, exclusive before), and the save owner (an intake datasource or a step's module). A document without a field never matches a filter on it. A contradictory filter, such as one metadata key required to equal two values or a window whose end is not after its start, is refused by name. One filter is not an exact match: a concept filter matches documents tagged with a SKOS concept or with one its expansion reaches, described under links and concept tags. The catalog evaluates filters and sort in SQL with keyset pagination, and access checks run on the results, so a page lists only documents the caller can read.
repo/proto v2 document_service.proto: ListDocumentsRequest, filter and sort
// Catalog filters; every set field must hold. Absent means no filter.
DocumentFilter filter = 7;
// Listing order. Absent means address order (DOCUMENT_SORT_FIELD_UNSPECIFIED).
DocumentSort sort = 8;
Sort is by call number (the default), commit time, or title, ascending or descending. Ties always break on the call number, compared as bytes and always ascending, so paging is stable even when many documents share a title. A page token is bound to the account, scope, filter, and sort it was issued under. Try it on four sample documents:
| Call number (graph / address / doc) | Title | Committed |
|---|---|---|
intake:acme / crm / d-104 | Q3 report | 10:42 |
intake:acme / crm / d-221 | (none) | 09:15 |
intake:acme / wiki / d-007 | Onboarding guide | 11:03 |
intake:acme / wiki / d-310 | Q3 report | 09:58 |
Call number order: graph id, then graph address id, then document id.
Links between documents, and concept tags
A document can point at other documents from inside its own typed content. A
link is a DocumentLink field in CORE, the typed
structured_data payload included, whose descriptor carries the
link field option from repo/v2/links.proto. The option names the
relation, checked as a link_relation value, and optionally the
structured_data types a target may hold. The schema says what a link means;
the value says where it points. A DocumentLink field without the option, the
option on a field of any other type, or a link under a map value refuses the save as
VALIDATION_FAILED.
repo/proto v2 links.proto: the link option and the link value (abridged)
Show the actual definition
extend google.protobuf.FieldOptions {
  // Marks a DocumentLink field (singular or repeated) as a link.
  LinkField link = 59100551;
}

message LinkField {
  string relation = 1;              // a link_relation name, required
  repeated string target_types = 2; // structured_data types a static target may hold
}

message DocumentLink {
  oneof target {
    StaticTarget static_target = 1;   // a call number, optionally a pinned revision
    DynamicTarget dynamic_target = 2; // a DocumentFilter and sort, resolved on read
  }
  optional string label = 3;          // display text, not part of the link's identity
}
A static target is a call number, optionally pinned to one revision. On
every save that writes or sources CORE, each static target is checked: it must be in the
saving account, exist unpurged, be readable by the saving caller, and hold the pinned
revision when one is named. Failing any of those rejects the save as
LINK_TARGET_NOT_FOUND, one reason for all of them, so a save cannot be used
to probe what access hides. When the field lists target_types, the target's
admitted structured_data type must be on the list, or the save is
LINK_TARGET_TYPE; that type is read from the catalog, so the check fetches no
part bytes. Both are recorded FAILED_PRECONDITION outcomes. A tombstoned
target is accepted and the link dangles. A dynamic target is a saved
filter: a DocumentFilter plus a sort, checked for consistency at save and
evaluated only when someone reads it.
The static links of each document's current revision project into a catalog edge table,
catalog_document_links, one row per link, named by field path and ordinal
(structured_data.sections[0].cites, element 2). A save that writes or
sources CORE replaces the rows, a save that carries CORE keeps them, a tombstone or purge
clears them, and CatalogEntryRebuild rebuilds them from the stored CORE part
with its retained schema. The target columns are a call number, not a foreign key, so a
target's later tombstone or purge writes nothing there; dangling is worked out when the
link is read. Dynamic links write no row and are never backlinks.
| Read | What it returns, under the reader's access |
|---|---|
ListLinks | A revision's links (current unless a revision is named), decoded with the schema that revision retained, in field-number order, then element order. A static link carries its target's state for this reader: current, target_tombstoned, or target_unavailable, which covers missing, purged and unreadable as one state. A dynamic link returns its selector unevaluated. |
ResolveLink | One page, up to 1,000, of a dynamic link's targets: its filter and sort run as a ListDocuments listing in the linking document's account, at read time. Tombstoned documents never match. Pointing it at a static link is FAILED_PRECONDITION. |
ListBacklinks | Static links into a document from the current revisions of documents the reader can read, optionally of one relation, ordered by linking call number, field path and ordinal. Edges the reader cannot see are dropped before paging, so a page never carries one. |
Concept tags and the concept filter
The SKOS ConceptRef from the well-known types (see
concept schemes) also serves as a document tag. A
ConceptRef value in CORE whose field rules bind it with
concept_schemes is decided at save against the concept schemes the host has
mounted: a concept the scheme lacks fails as concept.member and a scheme the
host has not mounted fails as concept.unmounted, both
VALIDATION_FAILED. Admitted tags project into
catalog_document_concepts under the same field path and ordinal identity as
links, for the current revision only, replaced, kept, cleared and rebuilt the same way.
Only the scheme and concept ids are stored, with no labels, ancestors or expansion, so a
scheme change needs no catalog rewrite.
An illustrative CORE schema: two link fields and one concept tag
message Memo {
  // A static link to the memo this one supersedes.
  DocumentLink replaces = 1 [(ai.protomolt.proto.repo.v2.link) = {
    relation: "replaces"
    target_types: "acme.docs.v1.Memo"
  }];
  // Static or dynamic: "everything tagged finance, narrower included".
  repeated DocumentLink references = 2 [(ai.protomolt.proto.repo.v2.link) = {
    relation: "references"
  }];
  // A subject tag, decided against the mounted "subject" scheme at save.
  ai.protomolt.proto.types.v1.ConceptRef subject = 3
      [(ai.protomolt.proto.validate.v1.field) = { concept_schemes: "subject" }];
}
DocumentFilter.concept takes a ConceptRef and an optional
ConceptExpansion. When each page runs, the concept is expanded against the
mounted schemes: always its exact_match closure and the deprecated concepts
whose replaced_by chain reaches it; with narrower set, its
in-scheme descendants, transitively; with close_match set, one hop of close
matches. The expanded set is then matched against the stored tags. The filter works in
ListDocuments and in ResolveLink, so a dynamic link over a
concept follows the scheme as it changes without touching a stored document. Each page
returns concept_evidence: how many concepts it matched against, the mounted
version of every scheme it consulted, and the cross-scheme mappings it had to skip. A host
with no mounts, or a queried scheme that is not mounted, is
FAILED_PRECONDITION; a concept the scheme lacks, or an expansion past the
mount's bound (10,000 concepts by default), is INVALID_ARGUMENT.
Only tags in CORE are catalogued. A ConceptRef bound with
concept_schemes in any other part is checked the same way at save
(membership in the mounted scheme and the canonical form of the reference) and stored
with the part, but it does not project into catalog_document_concepts, so a
concept filter does not find it. A CORE tag's field path is part of its catalog key,
and a path longer than 1024 UTF-8 bytes, or one containing a NUL character, fails the
save as concept-catalog-storable. Map values are not walked for tags, and a
bound tag reached from a map value through a typed Any fails the save
rather than being skipped.
A stock repository host mounts its schemes at boot from
DOCUMENT_PLATFORM_CONCEPT_SCHEMES (alias
PROTOMOLT_REPO_CONCEPT_SCHEME_PATHS): a comma- or semicolon-separated list
of directories (each immediate .pb or .binpb file is one
ConceptScheme, named by its file name), single files, or
schemeId=path pairs. Every scheme is validated as it mounts, and an
unreadable file, a duplicate scheme id or an invalid scheme stops the host from
starting. The set is read once at startup; changing it means a restart. An embedding
host can also pass ConceptSchemeMounts to
RepoServices.withConceptSchemes. With nothing configured, no schemes are
mounted: a save carrying a bound tag is refused as concept.unmounted and a
concept filter answers FAILED_PRECONDITION. Links do not depend on mounted
schemes.
Drives: the only path to object storage
A Drive binds four things: a bucket, a key prefix, a region, and a
credentials reference. The credentials themselves are never in any message; the
reference is resolved at IO time. Every account is provisioned with two drives at
creation: an intake drive for staged source material and a
pipeline drive for the claim-check bodies passed between hops. A custom
drive type exists for anything else. A save names a drive, and the service resolves it to
that drive's current storage namespace (a stack) and records the stack
in the catalog; callers never see it.
The house rule is strict: nothing but repo-service speaks S3. Drives are the only thing
that resolves to object-storage coordinates, so everyone else in the platform sees
drives and FileStorageReferences and nothing more. Swap the backing store
(MinIO, LocalStack, SeaweedFS, Ceph, rustfs, AWS itself) and only the drive config
changes.
Underneath the drives sits one storage seam, the BlobStore port: the only
surface business code and transport handlers use to touch blob storage, with no provider
SDK types crossing it. The port's own contract states the intent: a future backend, Azure
Blob or GCS or a packing decorator, is one new implementation, not a sweep through the
handlers. Document storage is S3-compatible: DOCUMENT_PLATFORM_BLOB_STORE
defaults to s3, which covers any S3-compatible store via an endpoint
override, and s3-redis-cache keeps S3 as the store of record with an
expendable Redis read-through, write-through cache in front of it. The port also has a
Redis provider, used by a bounded embedded archive profile and sample setups; it is not
a durable home for documents (its objects expire after an hour by default, and storage
that must retain data requires an S3 backing store). Retired or unknown values stop the
service at boot.
Document objects are write-once. Each part and each raw file is its own object in the
drive's documents namespace, and the catalog holds the only references to
them. A part carried into a new revision is the same object referenced again, so
unchanged parts cost nothing to keep.
Delete is a tombstone; purge is separate and deliberate
Deleting a document removes no bytes. DeleteDocument is itself a revision:
it carries an operation id, pins the exact revision it deletes, and commits a
tombstone accession with an optional reason. Earlier revisions stay in
the history, and ListDocuments leaves tombstoned documents out unless the
caller asks for them.
Removing bytes is PurgeDocument, an administrative operation. It is
idempotent by purge_id, and it is closed by default: the purge port denies
every request until an operator binds an admin identity, and ordinary process authority
cannot purge. Step through it:
Document state: TOMBSTONED
-
1. Tombstone
A caller sends
DeleteDocumentwith the revision it expects. A tombstone revision commits; no stored object is touched. -
2. Purge request
An administrator sends
PurgeDocumentwith apurge_idand a reason. Repeating the samepurge_idis safe. -
3. One catalog transaction
The document's references are marked purged. The response counts the references purged, the objects now eligible for deletion, and the objects retained because another document still points at them.
-
4. Bytes
Only objects with no unpurged reference left are deleted. The operation is two-phase and resumable, so an interrupted purge picks up where it stopped.
flowchart LR
          cur["Current revision"] -- "DeleteDocument" --> tomb["Tombstone revision: bytes kept"]
          tomb -- "PurgeDocument, admin only" --> refs["References marked purged"]
          refs -- "no other reference" --> gone["Object deleted"]
          refs -- "still referenced elsewhere" --> kept["Object retained"]
The purged mark is the only thing in the catalog that changes after it is written. Revisions, part references, and recorded outcomes are immutable, which is what lets a retry, an outcome lookup, and a history read all agree on what happened.
The archive: the same engine as a generic asset store
The ArchiveService is the repository family's general-purpose store, served
by the same binary and stored as ordinary v2 documents through
DocumentService, on the same drives, blob stores, and Postgres catalog. Its
hierarchy is account → archive → entry → version → rendition, where a
rendition is any one form of an entry: the raw file, a parsed protobuf, markdown, NDJSON,
parquet, anything.
Identity is the document call number. An entry address maps onto one v2 address field by
field, with no hashing: graph archive:<account>, the archive name, and
the entry id verbatim. Event ids, outcome keys and partitions derive from that call
number like any document's, and the stored objects behind it are write-once stack keys
the server allocates. EntryInfo.entry_uuid is left unset: the call number
is the only identity.
Where an archive entry lives
account_id        = EntryAddress.account_id
graph_id          = "archive:" + account_id
graph_address_id  = EntryAddress.archive
doc_id            = EntryAddress.entry_id
A rendition that does not change between versions is carried forward by reference: a
new version that adds a markdown rendition beside a large original keeps the original's
existing binding, with no bytes resent and no copy, so retained history costs only what
actually changed. Rendition names and sub-keys are path-safe names that admit no
/.
Each archive picks a versioning policy, and the policy decides what the
archive serves, never what is stored. Every revision is kept until an administrator
purge. VERSIONING_NONE shows the current revision only:
ListVersions returns one row, and a read at any other version answers
FAILED_PRECONDITION naming the policy, while the earlier revisions stay
readable through DocumentService by a caller with read access.
VERSIONING_RETAINED serves every version. Renditions have states too:
PRESENT, EMPTY, or DELETED, and the manifest of a
deleted rendition keeps its size, its hash, and a named reason. The map still lists the
file, the file is gone, and the hash proves what it was, which is what makes redaction
and retention auditable.
Every entry carries a classification state:
UNCLASSIFIED, DECLARED, IDENTIFIED,
VERIFIED, or CONFLICTED, never a silent default. A save can
declare a FormatFact, validated against the format's own rules (a
.zip filename can never claim tar), and ClassifyEntry re-reads
the primary rendition's bytes through the asset family's detection seam. The
classification is stored on the entry's CORE, so ListEntries filters by
state and GetArchiveStats counts entries per state exactly. Bridging
and catalog facets that sit on those classifications live on
Asset.
There are three upload doors, and the contract publishes no capability the service does
not implement: a unary PutEntry for small and medium payloads in memory,
a client-streaming UploadRendition (declare the size, optionally the
expected SHA-256 and, for the original rendition, a filename of at most 500 code points;
the bytes stream through to storage and nothing is staged on disk), and an
HTTP POST /v1/archive:upload where the body is the bytes, identity rides
query parameters or X- headers, Content-Length is required
(411 without it), and a binary protobuf UploadRenditionResponse comes back
with X-Operation-Id and X-Replayed response headers.
Reads come in two shapes. Unary GetEntry returns one version's manifest and
the selected renditions' bytes in a single response, which suits small renditions.
ReadRendition streams one rendition object (by name and sub-key) of one
version, whole or as a byte range. The first frame is a header naming the version, the
manifest's record of the rendition, the whole object's size and SHA-256, the range being
served, and whether that range is the whole object. Data frames of at most 64 KiB follow,
sent only while the client's flow control allows, so a slow reader stalls the storage
read instead of piling the object up in memory. A whole-object read is hashed as it
streams and ends in DATA_LOSS, not success, if the digest or length
disagrees with the manifest. A range read is checked for its length only and proves
nothing about the object's integrity, and the header says which kind of read it was.
Streamed rendition reads draw on the same per-host read byte budget as verified document
reads.
repo/proto archive_service.proto: the streaming read
// Stream one rendition object of an entry version, whole or as a byte
// range: a header frame, then data frames of at most 64 KiB, paced by the
// client's flow control. A whole-object read is checked against the
// manifest's SHA-256 before the stream completes.
rpc ReadRendition(ReadRenditionRequest) returns (stream ReadRenditionResponse);
One implementation serves the contract: DocumentArchiveGrpcService for
ArchiveService and DocumentArchiveMutationGrpcService for
ArchiveMutationService, in the protomolt-repo-archive module.
RepoServices mounts both on a stock repository host's gRPC port beside
DocumentService and DriveService, behind the same operator token
and caller resolution, and the HTTP archive upload route writes through the same
DocumentArchive (below). The archive keeps no tables of its own: Flyway
migration V121 drops the archives and archive_*
tables of the earlier ledger-backed archive. The bounded archive profile serves the same
two services on its own listener, with BridgeEntry,
UploadRendition and ReadRendition answering
UNIMPLEMENTED there.
Its mapping is a field copy with no hashing, and a save from any other surface naming an
archive: graph is refused by name.
The parsed rendition is the document's PARSED part, typed-validated like any
parser output; every other rendition is one raw blob in the BLOBS part, with
blob_id set to the rendition name, or the name and sub-key joined by
/. Each read is one v2 read per revision served, projected into the archive
view messages by the (sources) and (from) options on their
.proto and checked against the view's own validation rules; a projection
that fails or yields a view its rules refuse is DATA_LOSS naming the
message, field and rule.
Writes are thin translators into one v2 save each, and v2 save validation is the only
gate. PutEntry becomes one save. UploadRendition becomes one
streaming v2 UploadDocument: its header frame becomes the v2 upload header
and each chunk a v2 data frame, with the next archive frame requested only when the v2
call can take another, so a slow repository holds back the producer and the archive
stages nothing. GetEntry stays the small unary read, and
ReadRendition streams from ReadBlob (or the PARSED frames of
ReadDocument), re-framed to at most 64 KiB and checked against the
manifest's SHA-256 on a whole read. GetEntryManifest,
ListEntries and ListVersions are served the same way.
A write with a blank operation id gets a deterministic UUIDv5 derived from the request,
including the caller's requested expected_version, so a retry derives the
same id. Every write asks GetOperationOutcome first and replays a recorded
outcome whose content digest matches; a save that changes nothing records an unchanged
outcome instead of a new revision, which is what deduplicated reports, so
the archive does no deduplication of its own.
Archive definitions are v2 documents too. CreateArchive stores each
definition as a CORE-only document in the reserved graph
archive-def:<account_id> under the archive's name, carrying its versioning policy;
GetArchive reads it back and ListArchives pages through an
account's definitions. GetArchiveStats computes exact
counters by walking the archive's live documents: entries, versions, current bytes,
retained bytes, and object count and bytes per rendition, counting only the current
version of each entry when the archive's policy is VERSIONING_NONE. ListEntries fills
total_count for the archive, or for the requested
classification_state filter: from the single page when one page holds every
match, and otherwise by counting the archive's live documents page by page.
GetArchiveStats also reports exact per-state classification counts.
Classification lives in the entry's CORE, as the encoded Classification
under archive.classification and its state name under
archive.classification_state, which is indexed for the
ListEntries filter. An UploadRendition of the primary rendition
keeps only the 64 KiB head and 128 KiB tail of the bytes as they pass, classifies from
them, and sends the finished CORE in the v2 upload trailer, which v2 admits again before
the one commit. ClassifyEntry reads the primary rendition's byte windows
from the current revision, resolves the classification state machine, and commits a
CORE save. BridgeEntry refuses an entry whose classification names no
single format with FAILED_PRECONDITION, runs every applicable (or
requested) bridge against the primary rendition, and saves all derived renditions in
one BLOBS save.
On the mutation side, DeleteEntry becomes one v2
DeleteDocument, a tombstone revision that leaves earlier revisions and
their bytes in place, and GetArchiveMutation reads the recorded outcome
through GetOperationOutcome. DeleteRendition and
PruneVersions have no v2 counterpart under keep-forever retention: each
validates the request, checks that the archive and a live entry exist
(NOT_FOUND otherwise), records the refusal as its outcome, and answers
FAILED_PRECONDITION naming the call.
POST /v1/archive:upload streams the body into DocumentArchive
as one UploadRendition, chunk by chunk under flow control, and becomes one
v2 UploadDocument. It takes the rendition name, sub-key, schema subject,
module, operation id, expected version and expected SHA-256; it refuses
filename, title and source_uri with a 400 that
points to PutEntry for entry metadata. A scoped caller without write
permission on the archive's datasource is refused with 403 at header time, before any
of the body is read. The answer is the protobuf UploadRenditionResponse,
and the X-Operation-Id and X-Replayed headers say which
operation id the write used and whether it replayed a recorded outcome.
Who can read what: callers, accounts, sign-in
Every call to the repository host is made by a caller, and the host
decides what that caller may touch before it reaches storage. There are two kinds. The
operator presents the host's API token and runs with process authority,
which reaches every account. A scoped principal presents some other
credential, which the host resolves through an access policy file
(PROTOMOLT_ACCESS_POLICY) or by asking an OIDC provider to introspect the
token, in that order, first match wins. The operator token is
PROTOMOLT_API_TOKEN, and the repository's network listeners (the gRPC
port, the HTTP routes and the upload server) refuse to start when it is unset or blank,
so a stock host does not start an open repository listener.
Which accounts a scoped principal may reach is a separate document, the
account bindings file (PROTOMOLT_ACCOUNT_BINDINGS). It
maps each principal name to its account ids and to the identities that document access
rules match for it there (an email, a group, a Windows SID). A principal the file does
not name is bound to no account, and the file carries no secrets. Tenancy stays apart
from scopes: the credential says who you are, the bindings say where you may go.
protobuf/types authz/v1 account_bindings.proto: one principal's accounts (abridged)
Show the actual definition
// The accounts and ACL identities of one principal.
message AccountBinding {
  // The principal name exactly as the credential resolver reports it.
  string principal = 1;
  // The accounts the principal acts for; every other account refuses it by name.
  repeated string account_ids = 2;
  // The identities document access rules match for this principal inside
  // its bound accounts. Empty means only rules open to "public" match.
  repeated AclIdentity acl_identities = 3;
  // The intake owners the principal may save as, each in one of its bound
  // accounts. Empty means the principal reads but never writes.
  repeated IntakeWriterScope intake_writers = 4;
}

// One intake owner: a datasource in an account, optionally one connector,
// and whether the principal may create documents or only revise them.
message IntakeWriterScope {
  string account_id = 1;
  string datasource_id = 2;
  optional string connector_id = 3;
  bool allow_create = 4;
}
With bindings in place, the document, drive, and archive services answer a scoped
principal for its own accounts. Any other account is PERMISSION_DENIED with
the account named, a drive id outside those accounts looks missing, and inside an
account the document's own access rules still decide each read. Drive and archive writes
and administration still need process authority. Document writes (save, upload, delete)
need process authority or a credential-bound caller holding a writer grant for the
document's owner. A binding grants writes through intake_writers: for a
principal that lists any, the host registers one writer credential (issuer
repo-account-bindings) and one intake writer grant per listed owner, so a
console session or a scoped bearer principal passes the same writer check as any other
credential-bound caller, and each revision records the grant it was saved under. The
grants follow the binding: an owner removed from the list has its grant revoked the next
time the principal is bound, and one listed again gets a new grant id. A principal with
no intake_writers reads only; its writes reach the writer check and are
refused with WRITE_DENIED (PERMISSION_DENIED over gRPC, 403 on
the upload route). Purging a document still needs
the bound administrator identity described above. The account service
follows the same rule: a scoped principal can get and list only its bound accounts, and
the totals and paging of a list count only those.
Browsers sign in through the organisation's OpenID provider. The repository host serves
the routes under /console/session: login sends the browser to the provider
(authorization code with PKCE, state, and nonce), the callback checks the ID token's
issuer, audience, expiry, and nonce, introspects the access token, and issues a session
cookie (HttpOnly, Secure, SameSite=Strict). The session's principal is the same name a
bearer token would resolve to, so one bindings file covers both. The page reads its
principal and accounts from /console/session as binary protobuf and never
holds a token. Five PROTOMOLT_CONSOLE_* variables name the provider,
client, redirect, and session lifetime: set none and the sign-in routes answer 503 naming
them, set only some and the host refuses to boot.
The repository console
The repository role starts its HTTP port beside gRPC, and that port serves the
console bundle at /console from DOCUMENT_PLATFORM_CONSOLE_DIR.
The bundle is static and needs no credential, because the page has to load before anyone
can sign in and it contains no repository data. Without the variable the route answers
503 and names it; a directory without an index.html stops the boot.
The same port mounts a Connect gateway at /connect, which
is how the browser reaches the repository. Connect is a small HTTP protocol for calling
gRPC methods; here every message is binary protobuf, built from TypeScript stubs
generated from the same protos, with nothing transcoded on the way. The gateway exposes
exactly the 20 DocumentService, DriveService, and
ArchiveService procedures the console needs (a test pins the list): twelve
document calls (ListDocuments, GetManifest,
GetDocument, ListRevisions, ReadDocument,
GetSchemaDescriptor, ReadBlob,
GetOperationOutcome, DeleteDocument, ListLinks,
ResolveLink, ListBacklinks), ListDrives, and seven
archive reads. Any other method answers UNIMPLEMENTED there while staying
reachable over gRPC.
Each call runs under a caller resolved the same way as on the gRPC listener: bearer
credentials first, then the console session cookie when sign-in is configured. A
cross-site page cannot call it: browser requests that are not same-origin are refused
before any credential is read. The caller is resolved from the request headers alone,
before the gateway touches the body, so a request with a missing, unknown or expired
credential is refused as unauthenticated without the gateway reading or
buffering anything it sent, and a credential store outage answers
unavailable the same way. Those refusals use the ordinary Connect error
record.
Signed in, the Repository section works on live data through that gateway:
- Accounts: the accounts the signed-in session is bound to, read from
/console/session, with the principal named. Each account is marked read only or names the intake owners the session writes as there. There is no global account catalog. An account can still be opened by id, and the host refuses one the session is not bound to; a signed-out visitor gets a Sign in button. - Documents from
ListDocuments, with every lookup filter and sort above. A form value the server would refuse, such as a concept scheme without a concept, is refused by name before any call. Only documents the session's access identities may read are listed. The query is written to the page address, so a reload, the back button or a shared link lists it again from page 1; page tokens stay out of the address because each is bound to the query it was issued for. - Concept filter: a row of the listing form takes a scheme id and a
concept id, with checkboxes for narrower concepts and close matches, and sends them as
DocumentFilter.concept. Above the results the page shows what the expansion read: how many concepts it matched against, the mounted version of every scheme it consulted, and each mapping it could not follow. On a host with no schemes mounted the listing shows the server'sFAILED_PRECONDITION. - Concept schemes: the Look up page holds a scheme browser with two
halves. The lookup half runs concept-filtered
ListDocumentscalls for an account (scheme, concept, narrower, close match, an optional graph or graph address, and whether to include tombstoned documents) and shows the matches with the server's concept evidence, including the scheme versions the host has mounted. The hierarchy half decodes aConceptSchemethe operator supplies in the browser, as a.binpbor.pbfile or base64 text; the console does not fetch schemes from the server, so it shows the file it was given, which need not be the version the host mounted. For each concept it shows broader and narrower concepts, related concepts,replaced_by, notations, labels (hidden labels included), and the five cross-scheme mappings. A scheme or concept IRI becomes a link only when it is anhttporhttpsURL. - Document detail: the manifest's parts with state, size, SHA-256,
writing revision and owner; the validation record; revision history; and the raw
files. A part is decoded with the descriptor set its revision retained, fetched through
GetSchemaDescriptorand hashed again in the browser; unknown fields are listed, not dropped. - Links: a document's Links tab reads
ListLinksfor the revision shown, with each link's field path, relation, label and target. A static target shows its call number, any pinned revision, and its state for this reader:RESOLVED,TOMBSTONED, orUNAVAILABLE, one state for missing, purged and unreadable because the server does not tell them apart. A dynamic target lists its selector condition by condition, and Resolve dynamic target pages throughResolveLinkat the same revision, with the concept evidence when the selector names a concept. Below, backlinks fromListBacklinksname each linking document, its current revision, the field and relation, and the revision it pins. Targets and backlinks open in the console. A relation is shown as text, and only an absolutehttp:orhttps:relation URI becomes a link, opened in a new tab withrel="noopener noreferrer", so ajavascript:ordata:value never becomes anhref. - Compare: the document page's Compare tab sets the revision shown
beside another exact revision. It opens from History's Compare button or from a
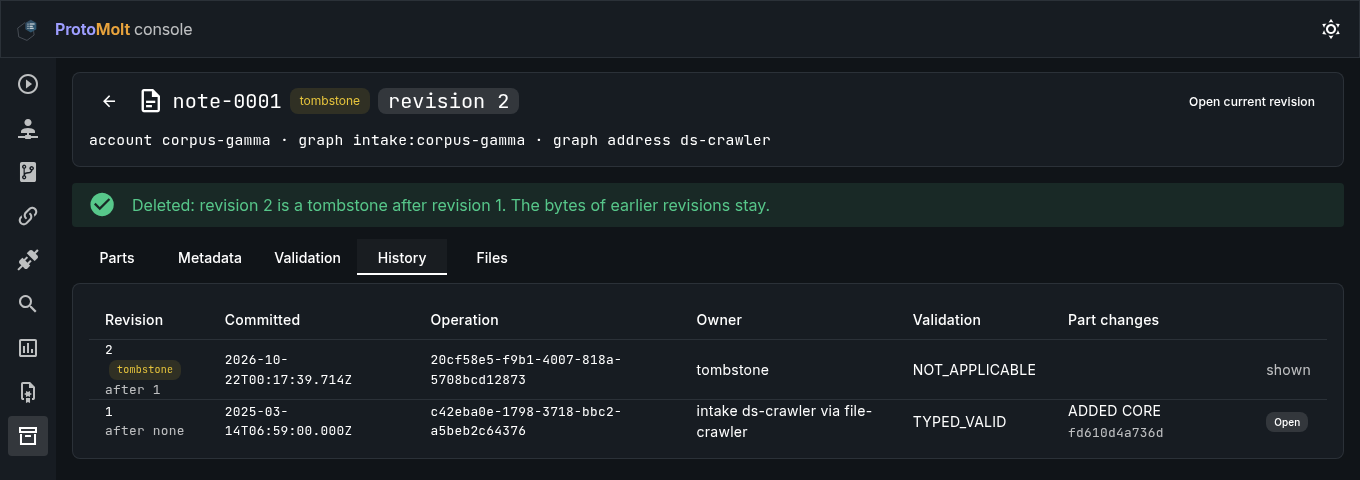
compare=<revision>parameter next torevisionin the page address, with Swap and Close; starting a comparison fixes the shown side at the revision on screen, and a compare value that is not a revision, or equals the one shown, is reported by name. The parts table matches the two manifests by selector and marks each part added, removed, changed or unchanged, naming the changed columns; line diffs follow for the search metadata, the bound concept tags, the outbound links, and the decoded CORE and PARSED fragments, each decoded with the schema its revision retained. A decoded fragment is flattened into onepath = valueline per set field, so the diff aligns changes by field path. A typedAnyis opened only when the revision resolved a schema for that exact payload: the same location (the part and every step of the field locator), type URL, payload length and SHA-256. AnAnywith no such match is shown as its type URL and length. AConceptReffield that declares concept schemes is also listed as a tag. Each side's manifest, CORE, PARSED and links are read at that one revision, and a section that fails to read is shown as that section's failure. Link lines leave out the target state, which describes the target as it is rather than as the revision saw it. - Delete: the current revision of a live document can be tombstoned
through
DeleteDocument. The confirmation names the call number and the revision it replaces and shows the operation id chosen when it opened, and the request expects exactly that revision. A stale revision is shown with a Reload button and never retried on its own; a failed send can be sent again under the same operation id, so it cannot record twice. The tombstone opens as the newest revision and earlier revisions keep their bytes; the console has no purge. The call runs as the signed-in caller and the host checks the account, the document's write access, and a writer grant for its owner. A session whose binding lists the document's intake owner inintake_writerscan tombstone; one whose binding lists none is refused withPERMISSION_DENIEDand its reason, as is any caller without a writer grant. - Files and renditions: previews read the first 64 KiB of a byte
range, and downloads stream
ReadBloborReadRenditionframes. A whole-file read must hash to the stored SHA-256; a range is shown as unverified. - Archives: stats, entries filtered by classification state, version history, and each version's renditions with state, size, SHA-256, and provenance.
- Look up: open a document by call number. Asking what happened to an
operation id is an account-page inspector, reachable by an
?operationId=link, that readsGetOperationOutcomeand states one of four answers. Committed names the result: a new document, a replacement of revision N, or Unchanged (the save matched an existing revision and wrote no new one), with a tombstone mark for a delete and a link that opens the revision. Rejected shows "Committed as a rejection" with the reason and each violation's rule id, field path and message, and says the save will not commit under that operation id. No outcome says that nothing terminal is recorded, that an outstanding request may still commit later, and that a mistyped id looks the same. A failed call says the lookup could not answer and gives the error.
The Upload screen, opened from an account, hashes a file in the browser, shows the
operation id before a byte is sent, and asks the upload route for a binary protobuf
receipt. The route resolves a console session the same way as the gateway, and the
session uploads as the intake owners its binding lists; before sending, the form says
whether the binding covers the datasource and connector entered. A session without a
matching owner is refused at the writer check with 403 WRITE_DENIED. A
session that creates a document grants each ACL identity its binding presents
READ and WRITE on it, so it can read and delete what it saved;
an upload that replaces a revision keeps that revision's access rules. The operator
token's uploads write no access rules.
For local work, the document platform's compose file has a dev profile
that runs a one-shot seeder: it writes a fixed fixture corpus (three accounts,
documents with revision histories, tombstones, raw files, semantic parts, and archive
entries) through the repository's real save code, so the console has something to
show. It runs only with PROTOMOLT_CORPUS_SEED=dev and refuses an account
that holds documents it did not create.
The captures below are the real console against a real repository host loaded with that fixture corpus, signed in through an OpenID provider.
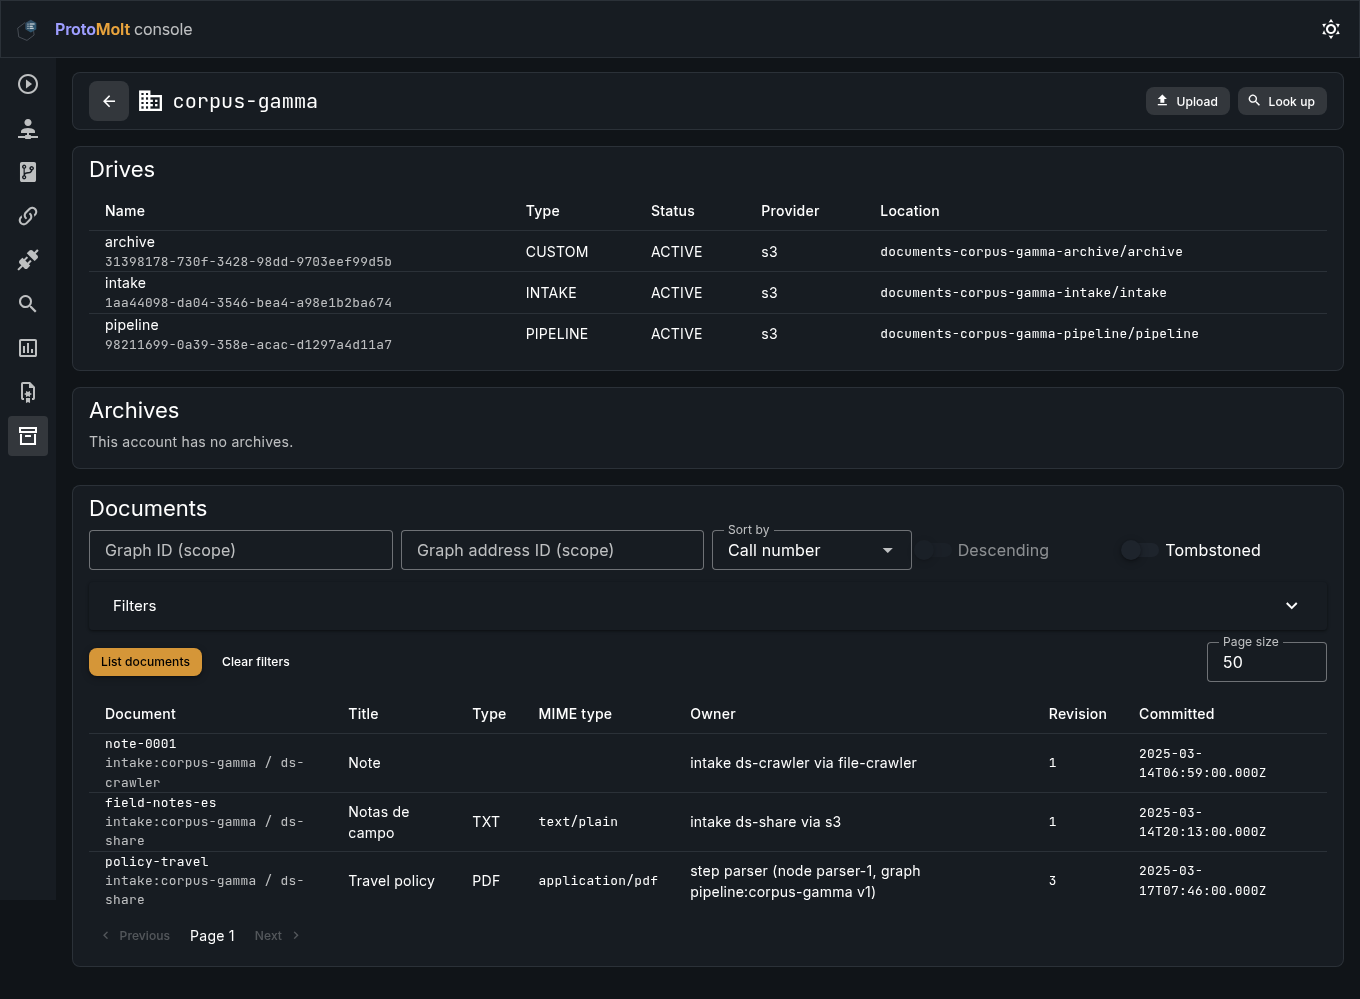
ListDocuments, each
row with its lookup fields and save owner. Fixture data.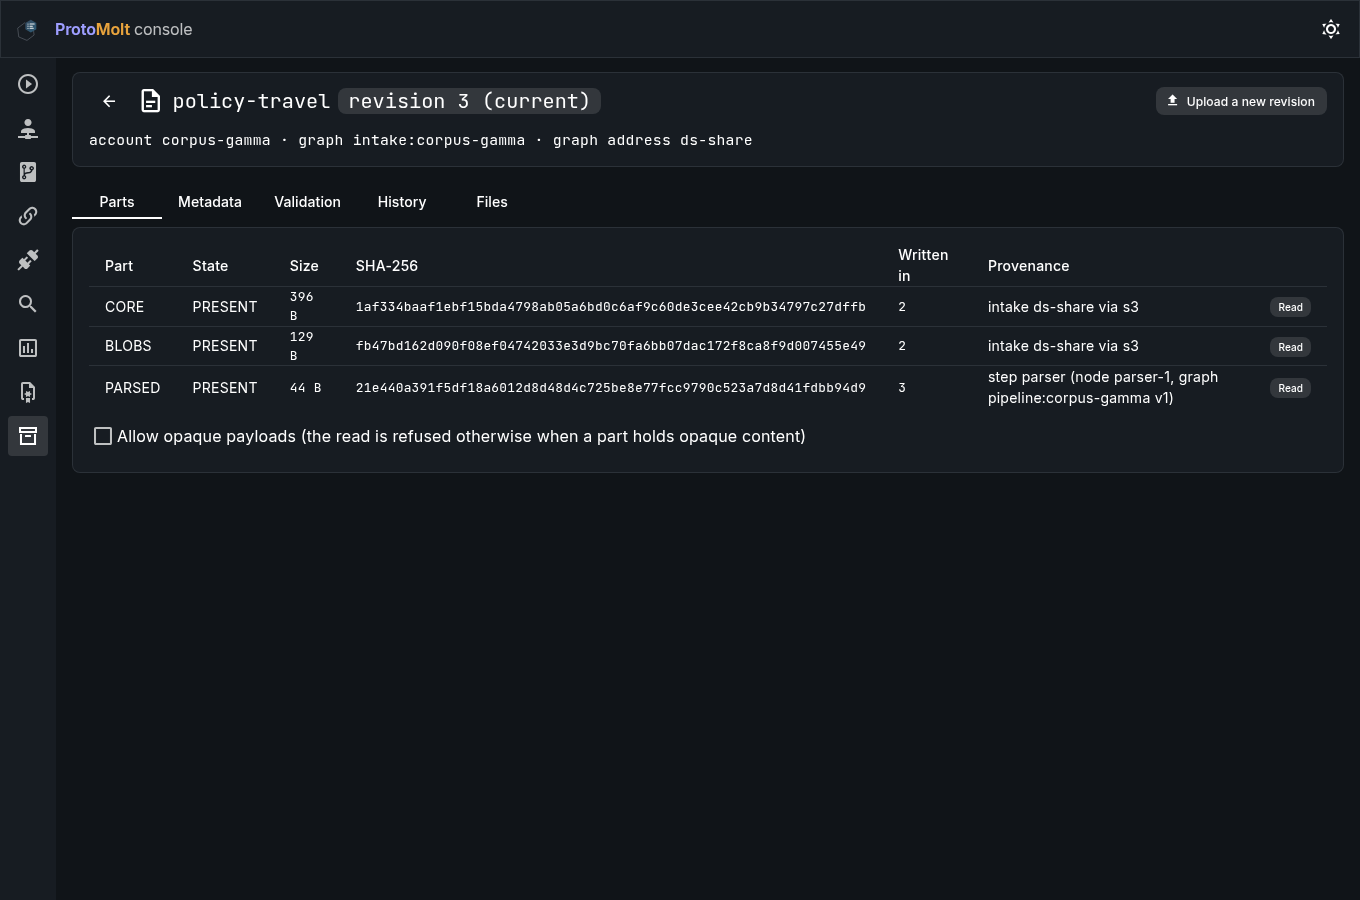
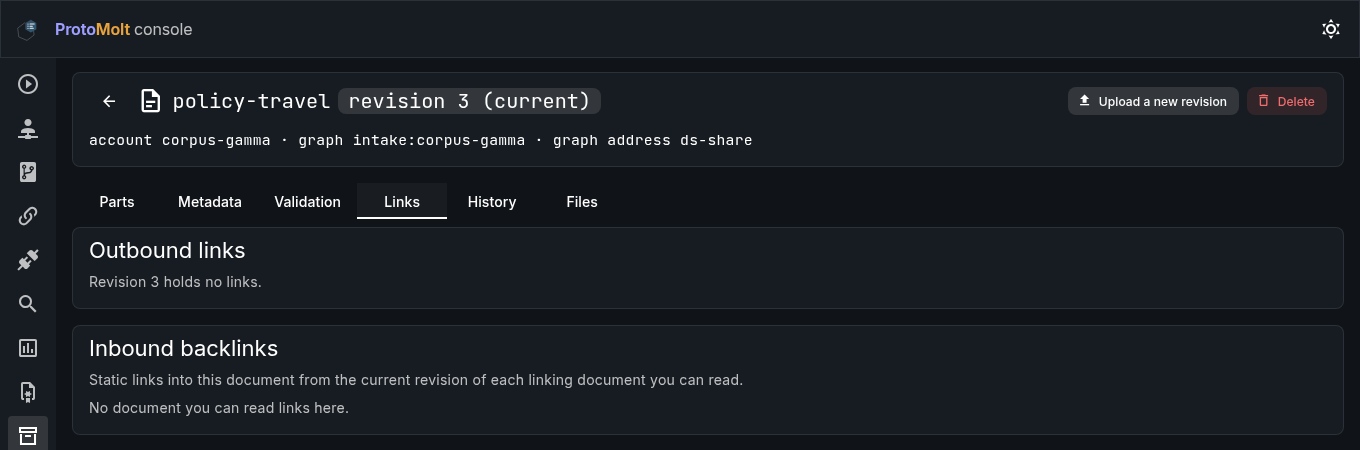
ListLinks for the revision shown and backlinks from
ListBacklinks; the fixture corpus saves no link fields, so both panels are
empty here.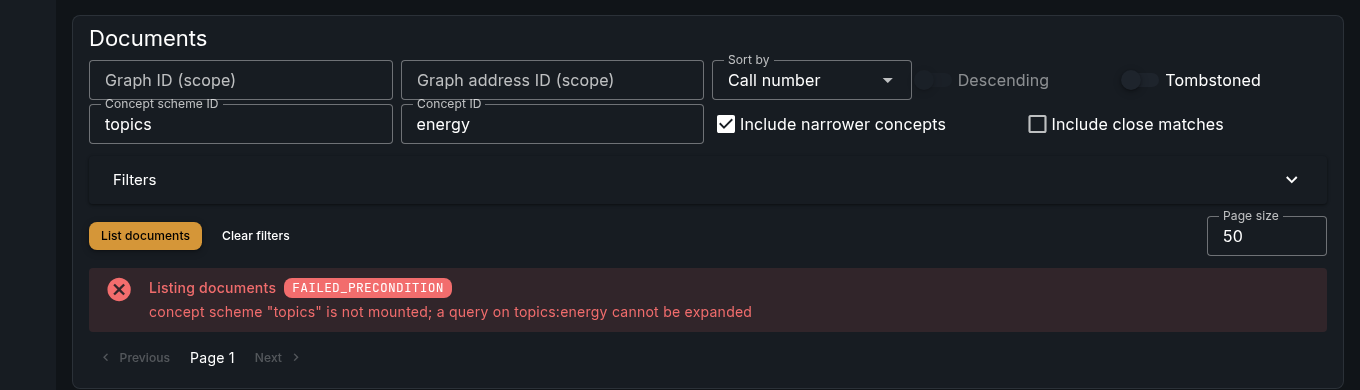
DOCUMENT_PLATFORM_CONCEPT_SCHEMES, so no concept schemes are mounted.
The listing asks for topics:energy with narrower concepts, and the host
answers FAILED_PRECONDITION because no scheme named
topics is mounted.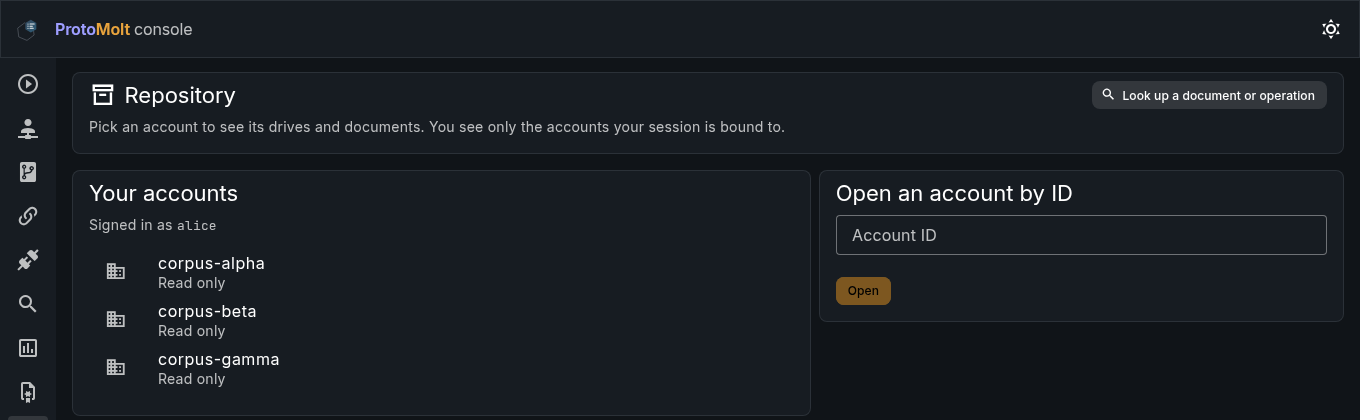
/console/session. Each is marked Read only because the fixture bindings
list no intake writers; the id form beside it opens an account directly.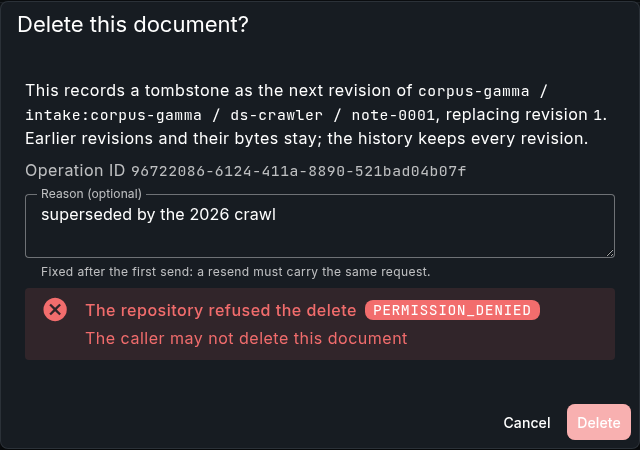
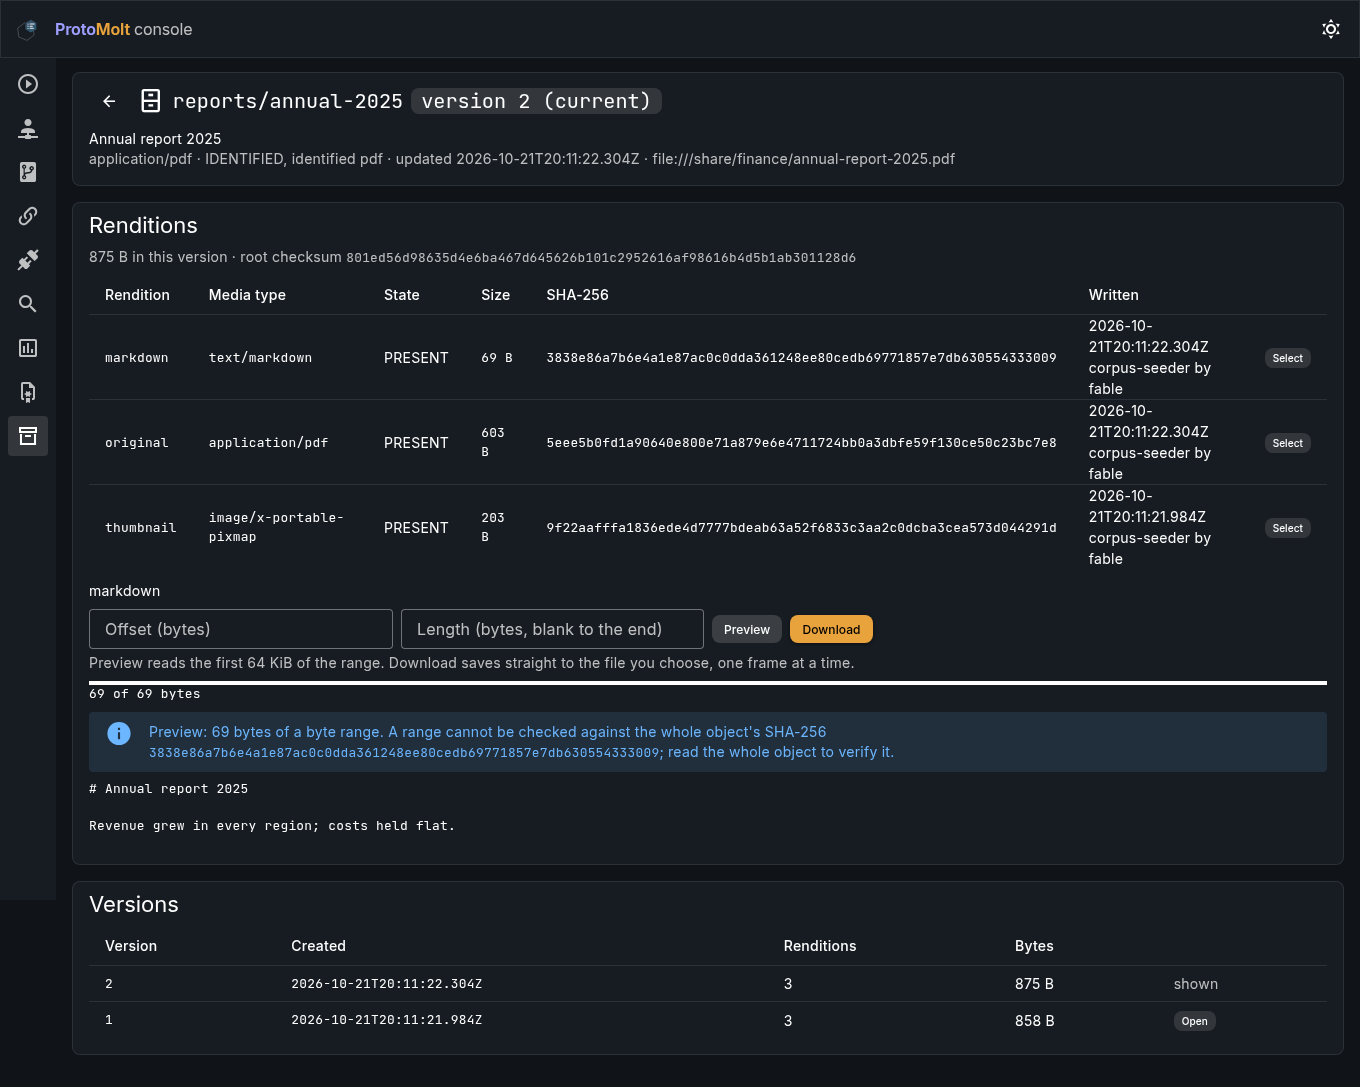
ReadRendition and says plainly that a byte range is not checked against
the whole object's digest.Encryption is the caller's choice
There is no encryption code inside repo at all. The service stores and serves opaque
bytes; if a caller needs confidentiality, it encrypts before storing and decrypts after
reading. The platform itself uses this pattern: the delegation transcripts of the
transform module, and the mesh cluster's event log, are sealed with AES-256-GCM inside
the ProtoMolt process and saved with SaveDocument as ordinary documents
whose CORE part carries the encrypted envelope. They are read back with
GetDocument, and each write compares and sets on the revision the writer
last confirmed. Encryption-at-rest is a codec layered on top of the document API, not a
repo feature, and a drive's credentials_ref likewise points at external
credential resolution, never at secrets in messages. Who may read and write is a
separate layer, covered above under callers and accounts.
Where the code lives
The document path is a handful of small Gradle modules under repo/, all
published as ai.pipestream:protomolt-repo-* and pinned by the ProtoMolt BOM:
| Module | Role |
|---|---|
protomolt-repo-proto | The wire contracts: Document, the v2 DocumentService, manifests, drives, the archive |
protomolt-repo-codec | Part layouts: splitting a message into parts and assembling it back |
protomolt-repo-accession | The DocumentService implementation: all 17 RPCs, including the link reads, the HTTP upload route, and the Kafka outbox relay |
protomolt-repo-catalog | The Postgres catalog: revisions, part references, outcomes, writer grants, and the outbox |
protomolt-repo-stack | Write-once stacks: streamed puts that return a reference, reads verified against it |
protomolt-repo-blob-s3, -cache, -redis | The storage providers behind DOCUMENT_PLATFORM_BLOB_STORE: S3, the Redis cache decorator, and the Redis provider it uses |
protomolt-repo-archive | DocumentArchiveGrpcService and DocumentArchiveMutationGrpcService: ArchiveService definitions, stats, entry reads and writes, and archive mutations over v2 documents, including classification and bridging. RepoServices mounts both on the gRPC port, and the HTTP archive upload route writes through the same DocumentArchive |
protomolt-repo-service | The service set and its wiring (RepoServices): gRPC on 9090; on 8080 the HTTP upload routes, the console bundle, and console sign-in |
Store coordination state through the repository
The repository's S3-compatible blob adapter stores bytes behind the document service. The delegation runtime uses that service to save encrypted transcripts and restore recorded tasks, cursors, and sequence state. A configured repository or encryption-key error fails startup; the runtime does not silently switch to memory.
An enabled mesh directory can use the same repository configuration for its encrypted event log. Without repository configuration, delegation transcripts and mesh events stay in memory. Persistent storage is one part of recovery; it does not imply automatic task failover between machines.
Implementation: S3 blob adapter, delegation persistence, and mesh persistence. See the storage setup guide for the separate registry, workflow evidence, jobs, and coordination settings.